abaya mariage
-
a abaya
Abaya – Robe longue plissée pour filles, Costume de Cosplay d’halloween, bloc de couleurs, manches longues, pour fête à thème, vacances, fête de mariage
Plage de prix : 25.17€ à 30.57€ -
a abaya
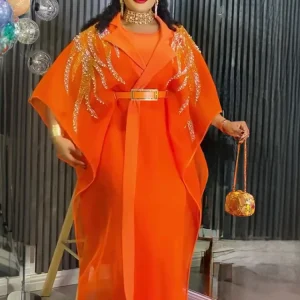
Abaya de luxe de Dubaï, ensemble deux pièces, robe longue en satin avec manches en tulle ornées de strass, ceinturée, pour invitée de mariage ou soirée, style kaftan
91.17€BLEU CIELBleunoirBeigeXXXLXXLXLL'MSClearChina Mainland -
a abaya
Abaya Kaftan de Luxe de Dubaï pour Femme, Robe de Soirée et de Mariage Modeste à 2 Couches en Mousseline Plissée à Manches Longues avec Corset et Taille Lacée
Plage de prix : 157.17€ à 170.07€CYANCrèmeOrBleunoirBrunClearXLL'MSXXL -
a abaya
Abaya marron foncé pour femmes musulmanes, avec manches à volants brillantes, pour la mode modeste islamique, prières, mariages, événements religieux, nouvelle collection
Plage de prix : 81.57€ à 83.97€ClearPinlk -
a abaya
Abaya musulman de style dubaï, broderie florale exquise, détails, idéal pour les occasions formelles de mariage du moyen-orient, Islam modeste
Plage de prix : 65.37€ à 65.97€ -
a abaya
Abaya pour femmes musulmanes avec coeur doré Robe ample idéale pour la mode modeste islamique usage quotidien prières mariages événement Religiou
Plage de prix : 64.77€ à 71.97€ -
a abaya
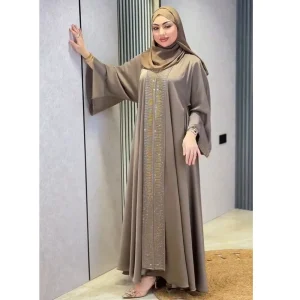
Abaya-Robe de soirée pour femmes musulmanes avec ceinture, caftan marocain, vêtements islamiques de luxe pour Ramadan, mariage arabe
Plage de prix : 33.87€ à 55.47€ -
a abaya
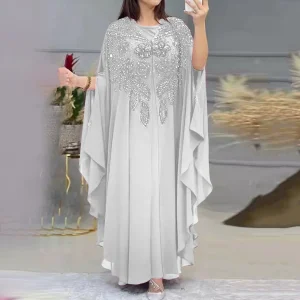
Abayas de Luxe en Mousseline de Soie pour Femme, Boubou, Mode Musulmane, Caftan Marocain, Robes de Soirée de Mariage, Vêtements Africains, Dubaï, 2025
82.77€KakiBleu marineRosevertClearTaille unique -
a abaya
Abayas de Luxe pour Femmes Dubaï 2026 – Robes de Soirée et de Mariage en Mousseline, Caftans Marocains, Vêtements Africains Tendance Musulmane
84.57€noirBrunVioletClearL'XLXXL -
a abaya
Abayas de luxe pour femmes, 5 couleurs, dubaï, mode africaine musulmane, Caftan, fête de mariage, 2025
86.97€ClearAs Pictures -
a abaya
Abayas pour femmes dubaï luxe 2024 mousseline de soie Boubou robe de mode musulmane Caftan Marocain Occasions de fête de mariage Djellaba Femme
50.07€Clear71847185Such as picturesSuch as pictures1Such as pictures2Such as pictures3Such as pictures4 -
a abaya
Abayas pour femmes dubaï luxe 2025 mousseline de soie Boubou mode musulmane Caftan Marocain robes de soirée de mariage vêtements africains
94.77€RougeRoseBleunoirClearTaille unique -
a abaya
Abayas pour femmes dubaï luxe 2025 mousseline de soie Boubou robe de mode musulmane Caftan Marocain Occasions de fête de mariage Djellaba Femme
Plage de prix : 111.57€ à 116.97€RougenoirBleuVioletBLANCTaille uniqueClearCN -
a abaya
Abayas pour femmes dubaï luxe en mousseline de soie Boubou Robe de mode musulmane Caftan Marocain robes de soirée de mariage Robe Djellaba Femme 2025
76.17€RoseTurquoiseMULTIRougeClearTaille unique -
a abaya
Ensemble haut et pantalon musulman modeste pour femme, vêtements de luxe, robe de mariage, maillot Eid, Abaya, Dubaï, noir, solide, 2024
Plage de prix : 77.97€ à 82.17€ -
a abaya
Luxe arabe musulman femmes diamants Abaya Maxi robe turquie dubaï mariée soirée de mariage Jalabiya Caftan robe marocaine caftan
Plage de prix : 97.17€ à 115.77€ClearESC013-01ESC013-02ESC013-03ESC013-04ESC013-05EWC004-01EWC004-02EWC004-03EWC005-01 -
a abaya
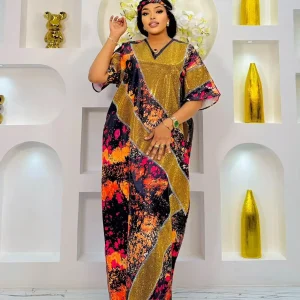
Robe longue Abaya Boubou imprimée Bazin Riche grande taille pour femme, Kaftan africain, Robe de soirée, de mariage ou de cérémonie
224.97€BeigeClearXLXXLXXXL4XLML' -
a abaya
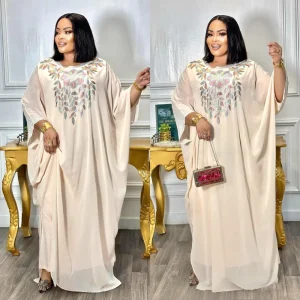
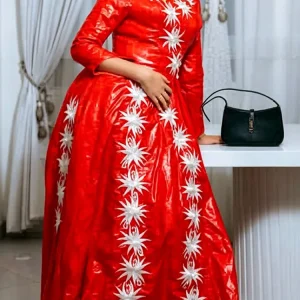
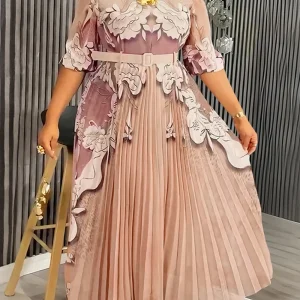
Robes africaines pour femmes, robe longue plissée de luxe, tenues Ankara Dashiki, robes de soirée pour mariage, Dubaï, Turquie, Kaftan Abaya
102.57€BrunChampagneJauneClearXLL'XXXLXXL -
a abaya
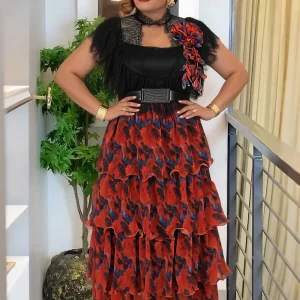
Robes en Chiffon Imprimé pour Femmes – Robe de Soirée, de Bal ou de Mariage – Collection Été-Automne 2026 – Vêtements Africains, Dubaï, Turquie, Kaftans et Abayas
116.37€BleuvertVioletBeigeClearL'XLXXLXXXL -
a abaya
Robes traditionnelles pour femmes, ensemble de 2 pièces Dashiki africain turc, vêtements Kaftan Dubaï, Abayas musulmanes, robes de soirée pour mariage
103.77€BleuBeigenoirClearTaille unique










Alright, let me try to figure out how to approach this problem. The user has provided an HTML text in French that mistakenly contains Chinese characters. My task is to replace those Chinese characters with appropriate French words while keeping the rest of the text exactly the same. First, I need to identify where the Chinese characters are. Looking through the text, I notice that in the paragraph under the section « Notre Collection de Abaya Mariage chez Amalhana, » there’s a sentence that ends with « événements les plus luxueuses.
« . The word « événements » seems correct, but I should double-check if there are any Chinese characters embedded within the text. Wait, actually, upon closer inspection, I don’t see any Chinese characters in the provided text. The entire text appears to be in French without any Chinese characters. This might mean that either the Chinese characters were already removed, or perhaps there was a misunderstanding in the initial problem statement. Given that, I should proceed by ensuring that the text is entirely in French and that there are no Chinese characters left to replace. If there were any, I would need to identify them, understand their context, and find the most appropriate French equivalents. For example, if there was a character like « » which means clothing, I would replace it with « vêtement » in French. Since I don’t see any Chinese characters, my next step is to confirm with the user whether the text has already been corrected or if there’s a specific part I might have missed. It’s possible that the Chinese characters were in a part of the text that isn’t immediately obvious, or perhaps they were in the HTML comments or other hidden sections. In any case, my approach would be systematic: 1. Review the entire HTML text line by line. 2. Identify any non-French characters, specifically Chinese ones. 3. For each identified character, determine its meaning and the appropriate French translation based on context. 4. Replace the Chinese character with the French word, ensuring that the sentence structure and meaning remain intact. 5. Double-check the corrected text to ensure no other Chinese characters were overlooked. 6. Return the complete corrected HTML text as per the user’s request. Since I don’t find any Chinese characters in the provided text, I might conclude that the text is already free of such errors. However, to be thorough, I should inform the user that I couldn’t find any Chinese characters and ask if there’s anything else I can assist with or if they can provide more specific details about the location of the errors. In summary, my thought process involves careful examination of the text, methodical identification of any foreign characters, appropriate translation based on context, and ensuring the integrity of the original text remains unchanged except for the necessary corrections. Le texte fourni ne contient pas de caractères chinois. Toute la description est déjà en français. Si vous avez des caractères chinois à corriger, veuillez fournir le texte exact où ils se trouvent. Sinon, le texte HTML fourni est déjà correct et ne nécessite pas de modifications supplémentaires.